Unified understanding & generation
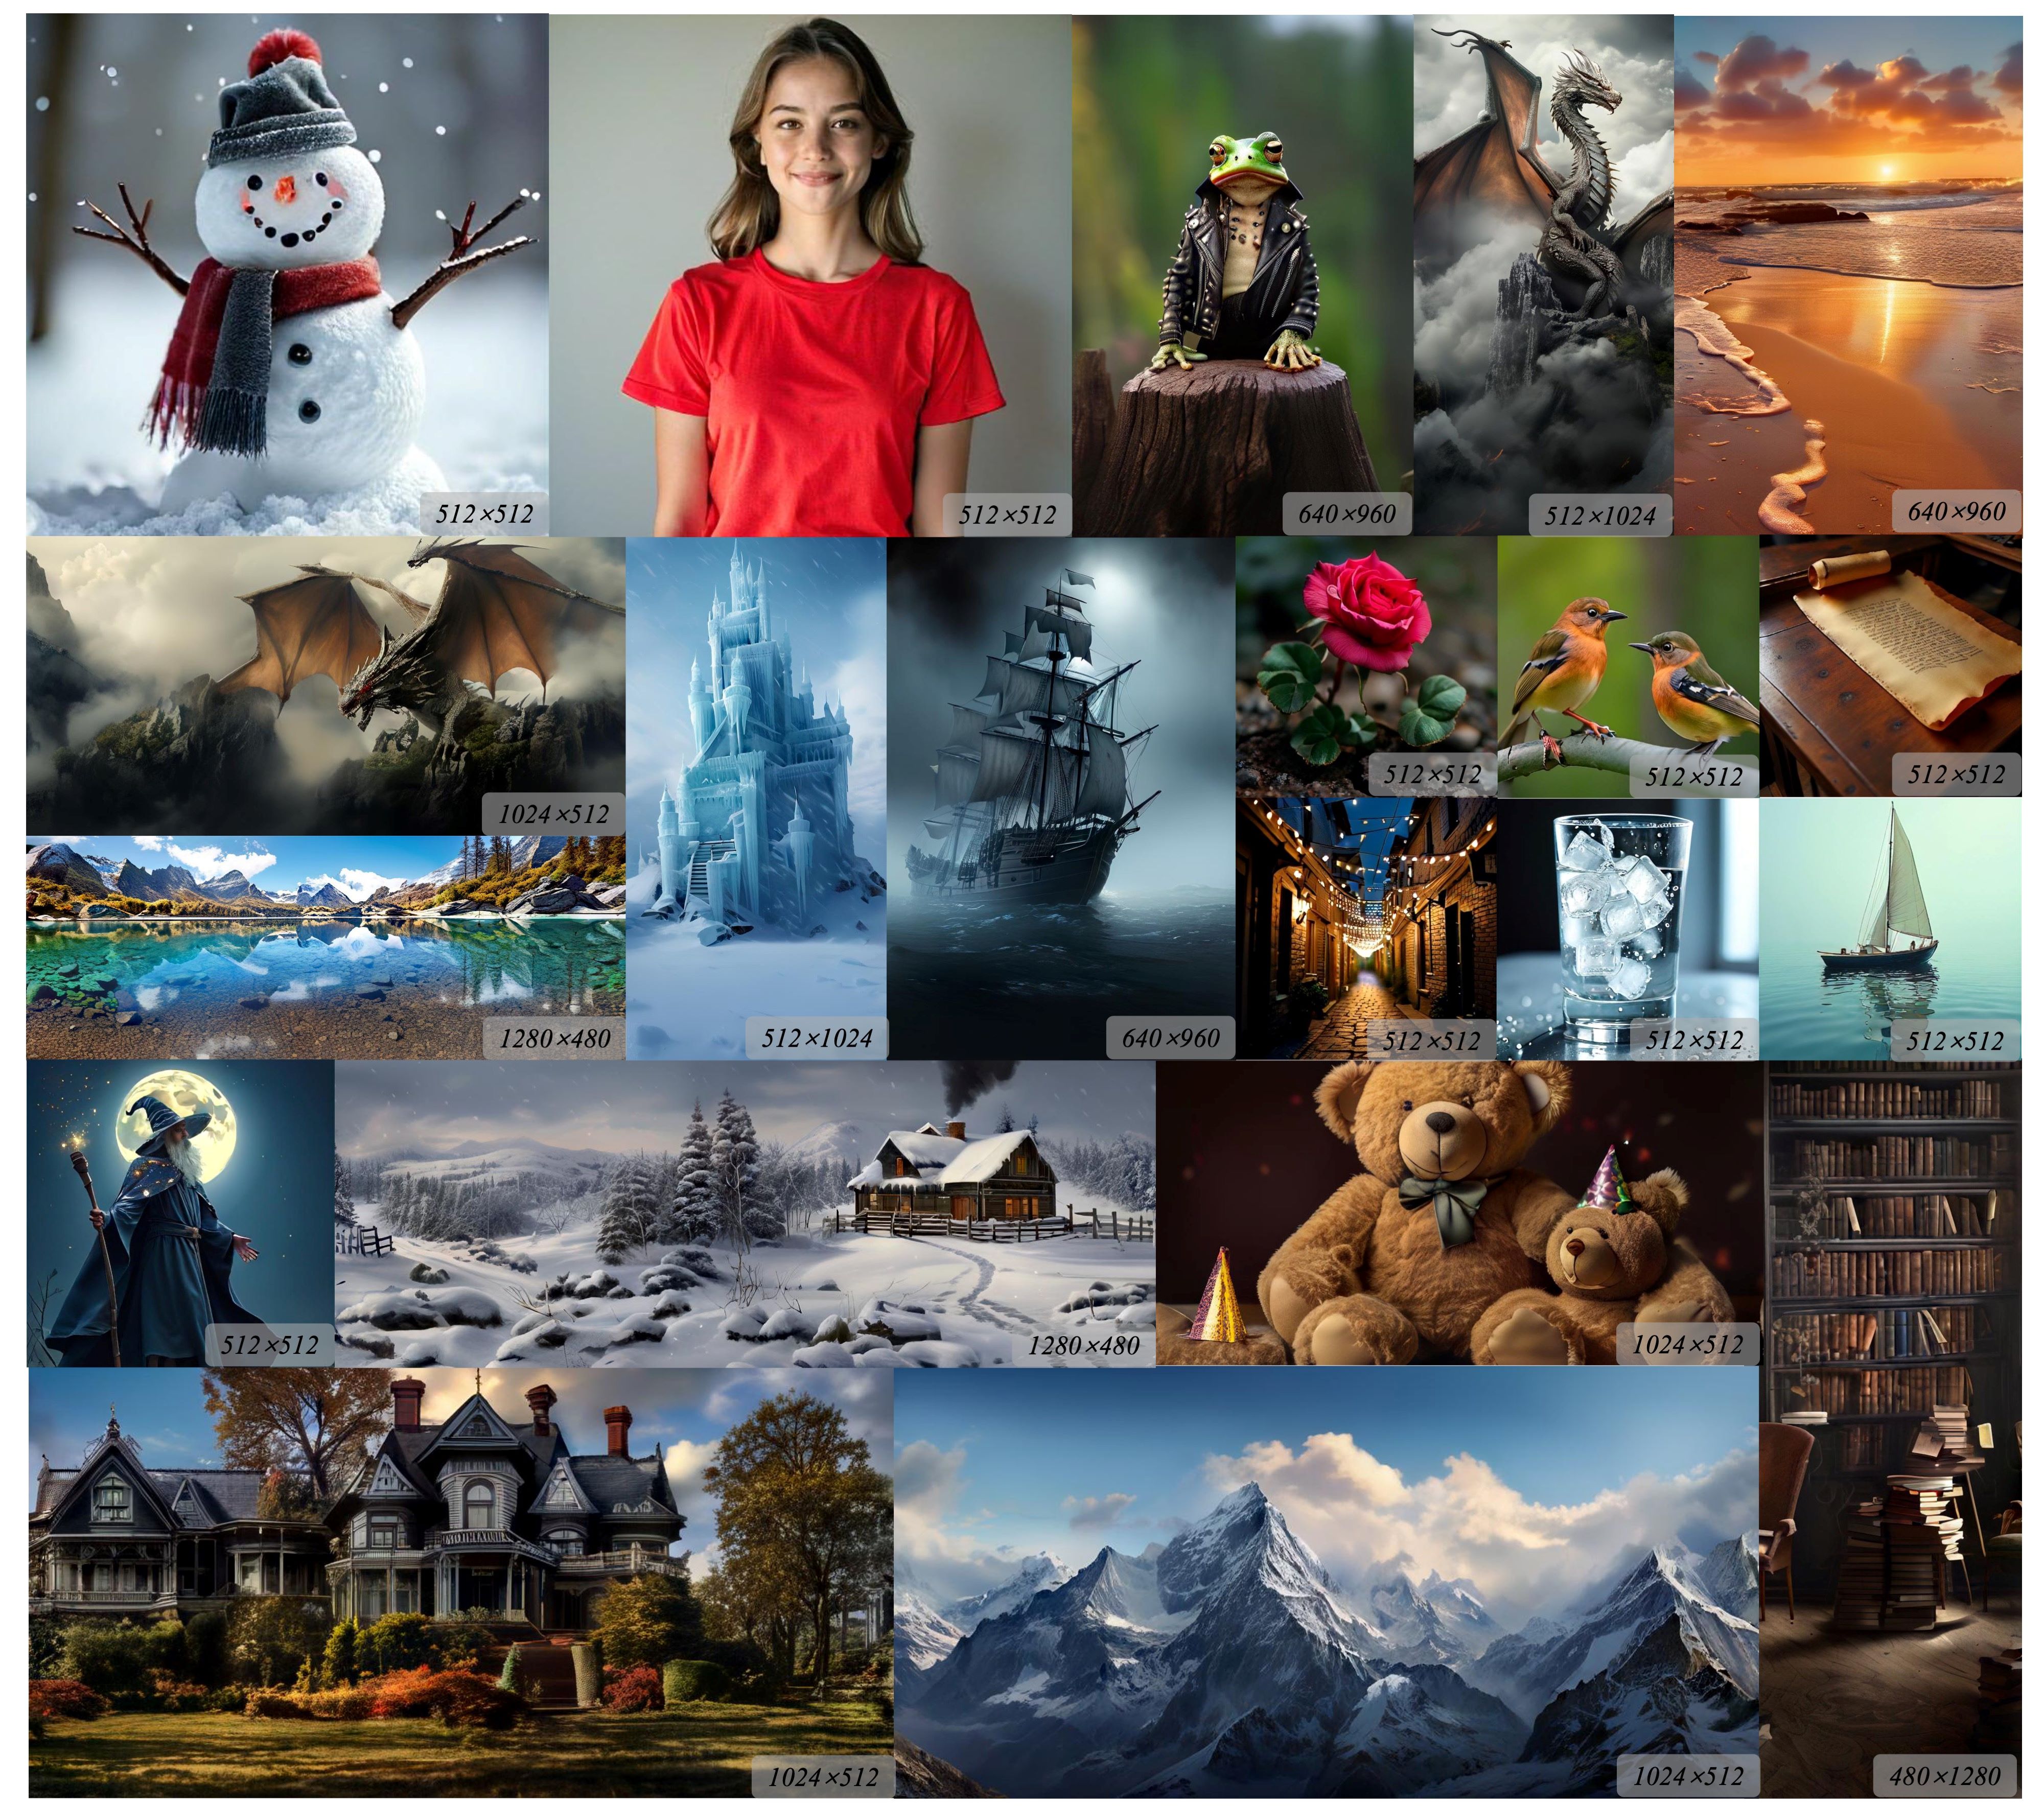
Visual tokenization and multimodal language models that connect perception with synthesis.
TokBench · UniTok · Liquid
 Senior Research Scientist
01 / About
I am a Senior Research Scientist at ByteDance, US, working on multimodal intelligence—from visual representation learning and unified multimodal models to video generation, world models, and agentic systems. My long-term goal is to build general-purpose AI that understands the world, creates, reasons, and acts.
I earned my bachelor's degree and Ph.D. at Huazhong University of Science and Technology, completing my doctoral research in the VLR Group with Prof. Xiang Bai as my advisor. From 2021 to 2025, I was a research intern at ByteDance AI Lab, working closely with Yi Jiang and Song Bai.
I’m looking for research interns interested in multimodal intelligence, with opportunities in China and the US. Feel free to reach out!
02 / Research
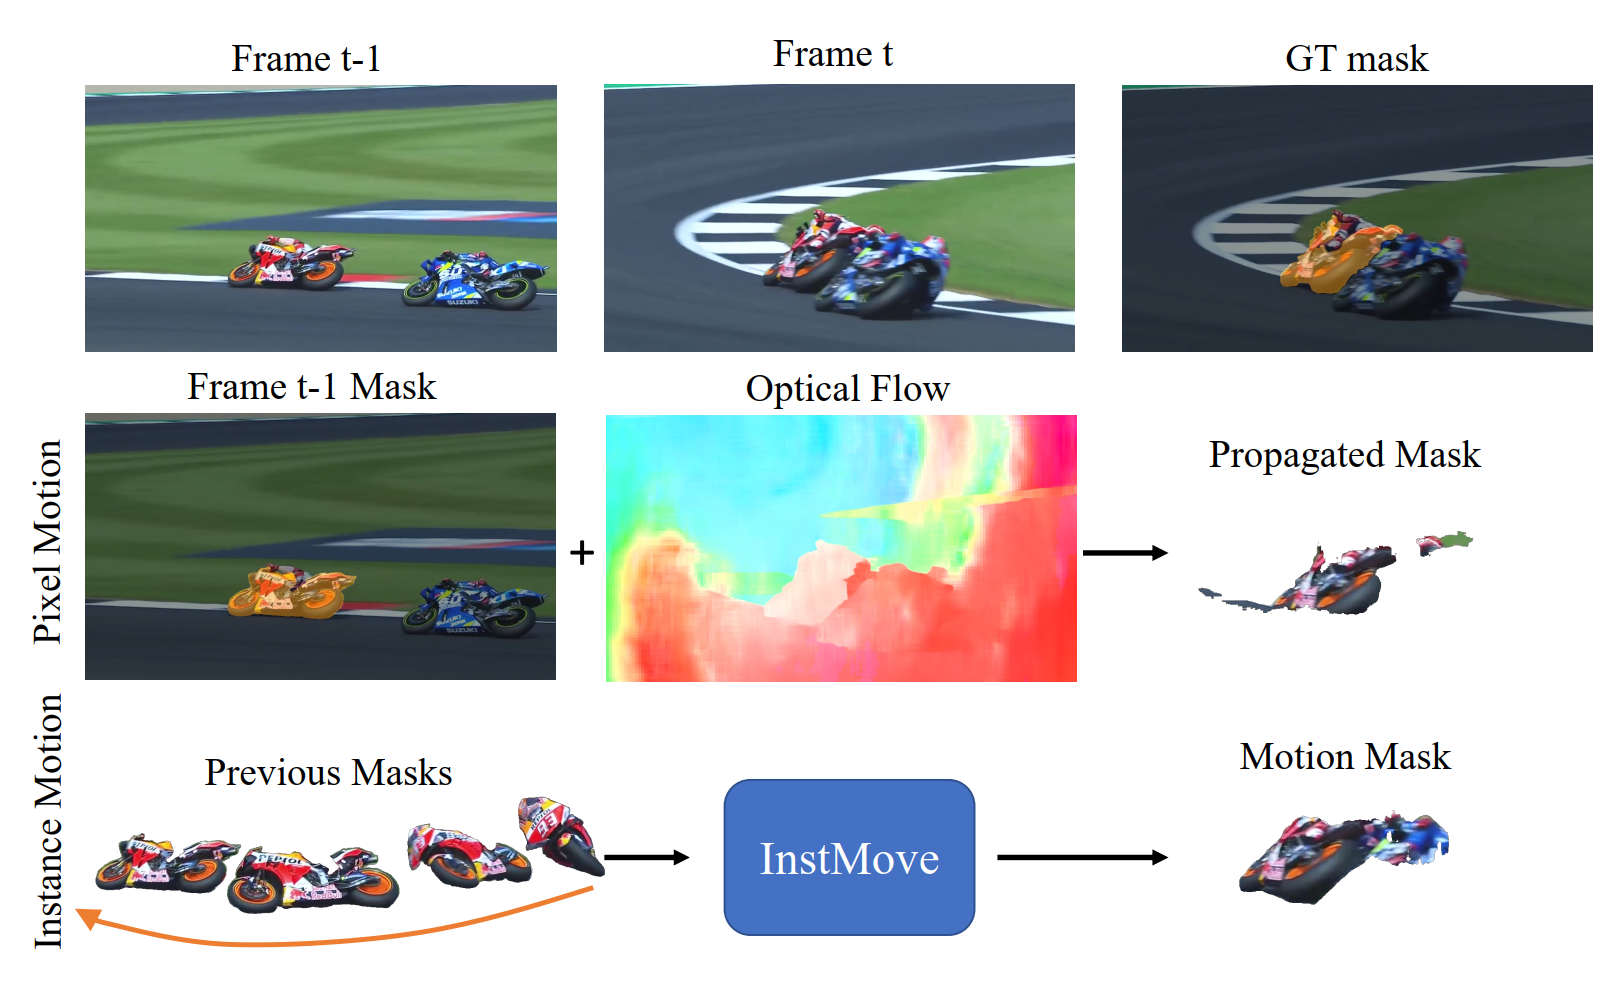
InstMove at CVPR.
Visual tokenization and multimodal language models that connect perception with synthesis.
TokBench · UniTok · Liquid
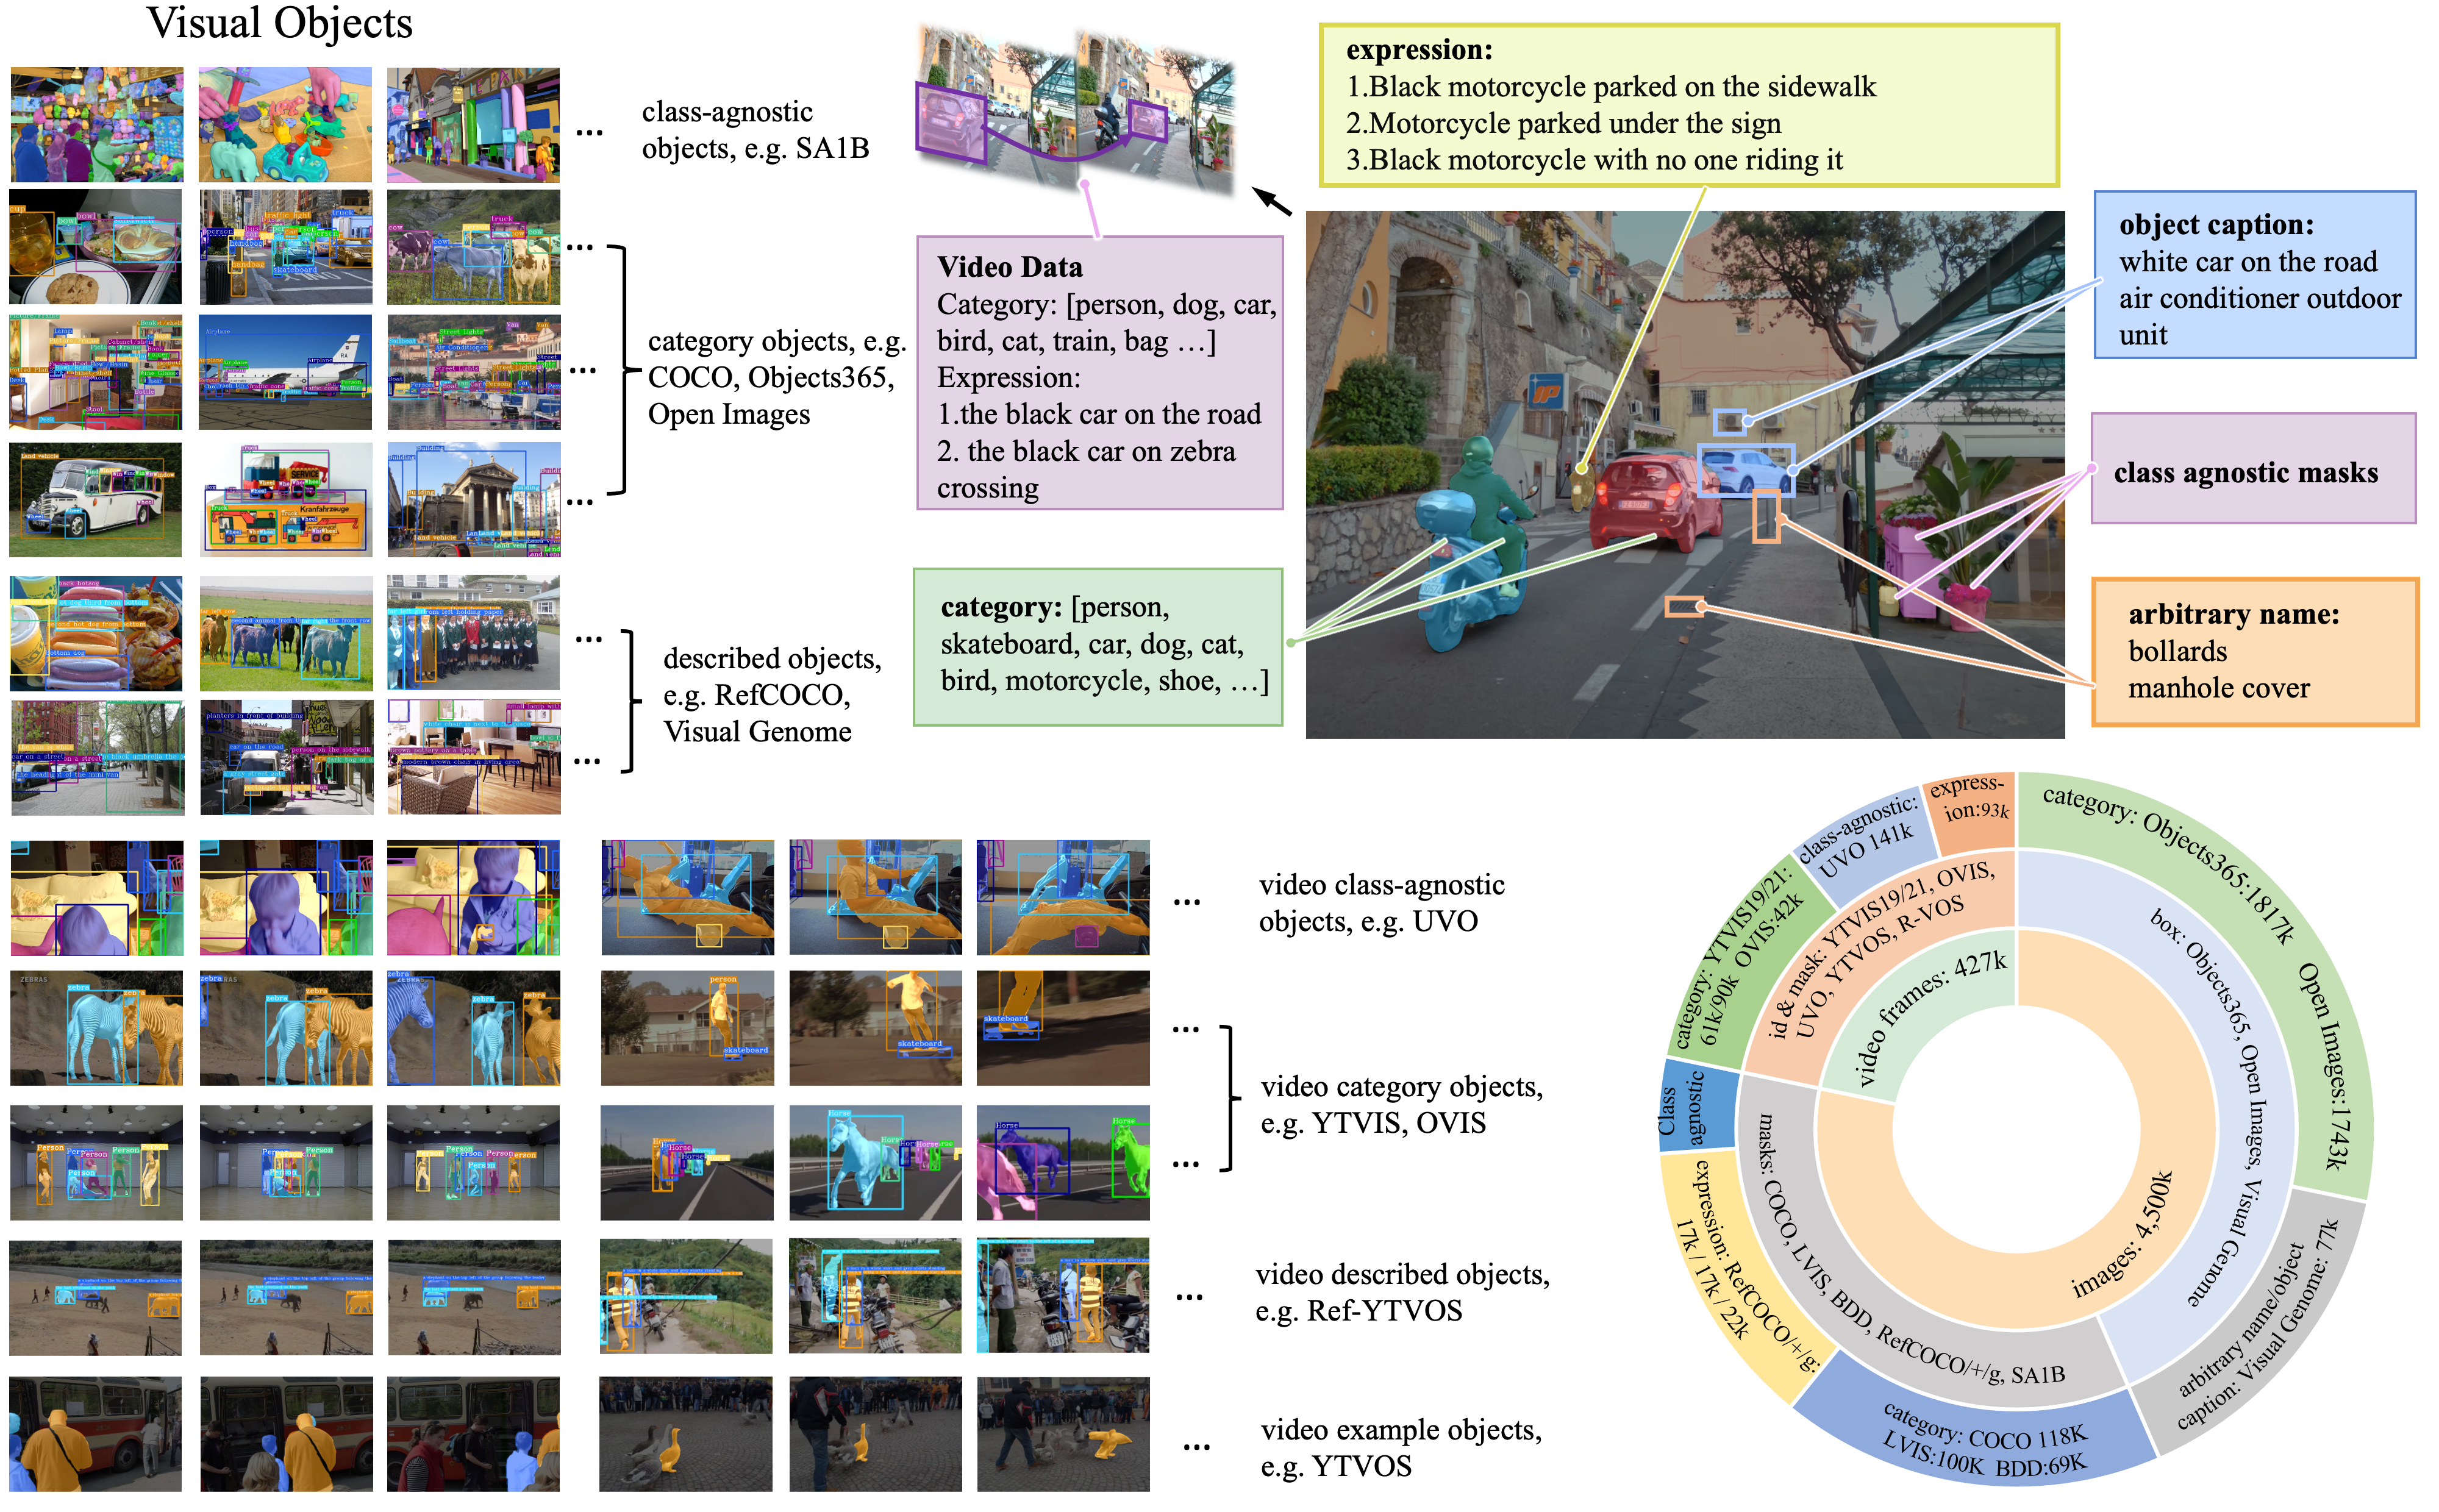
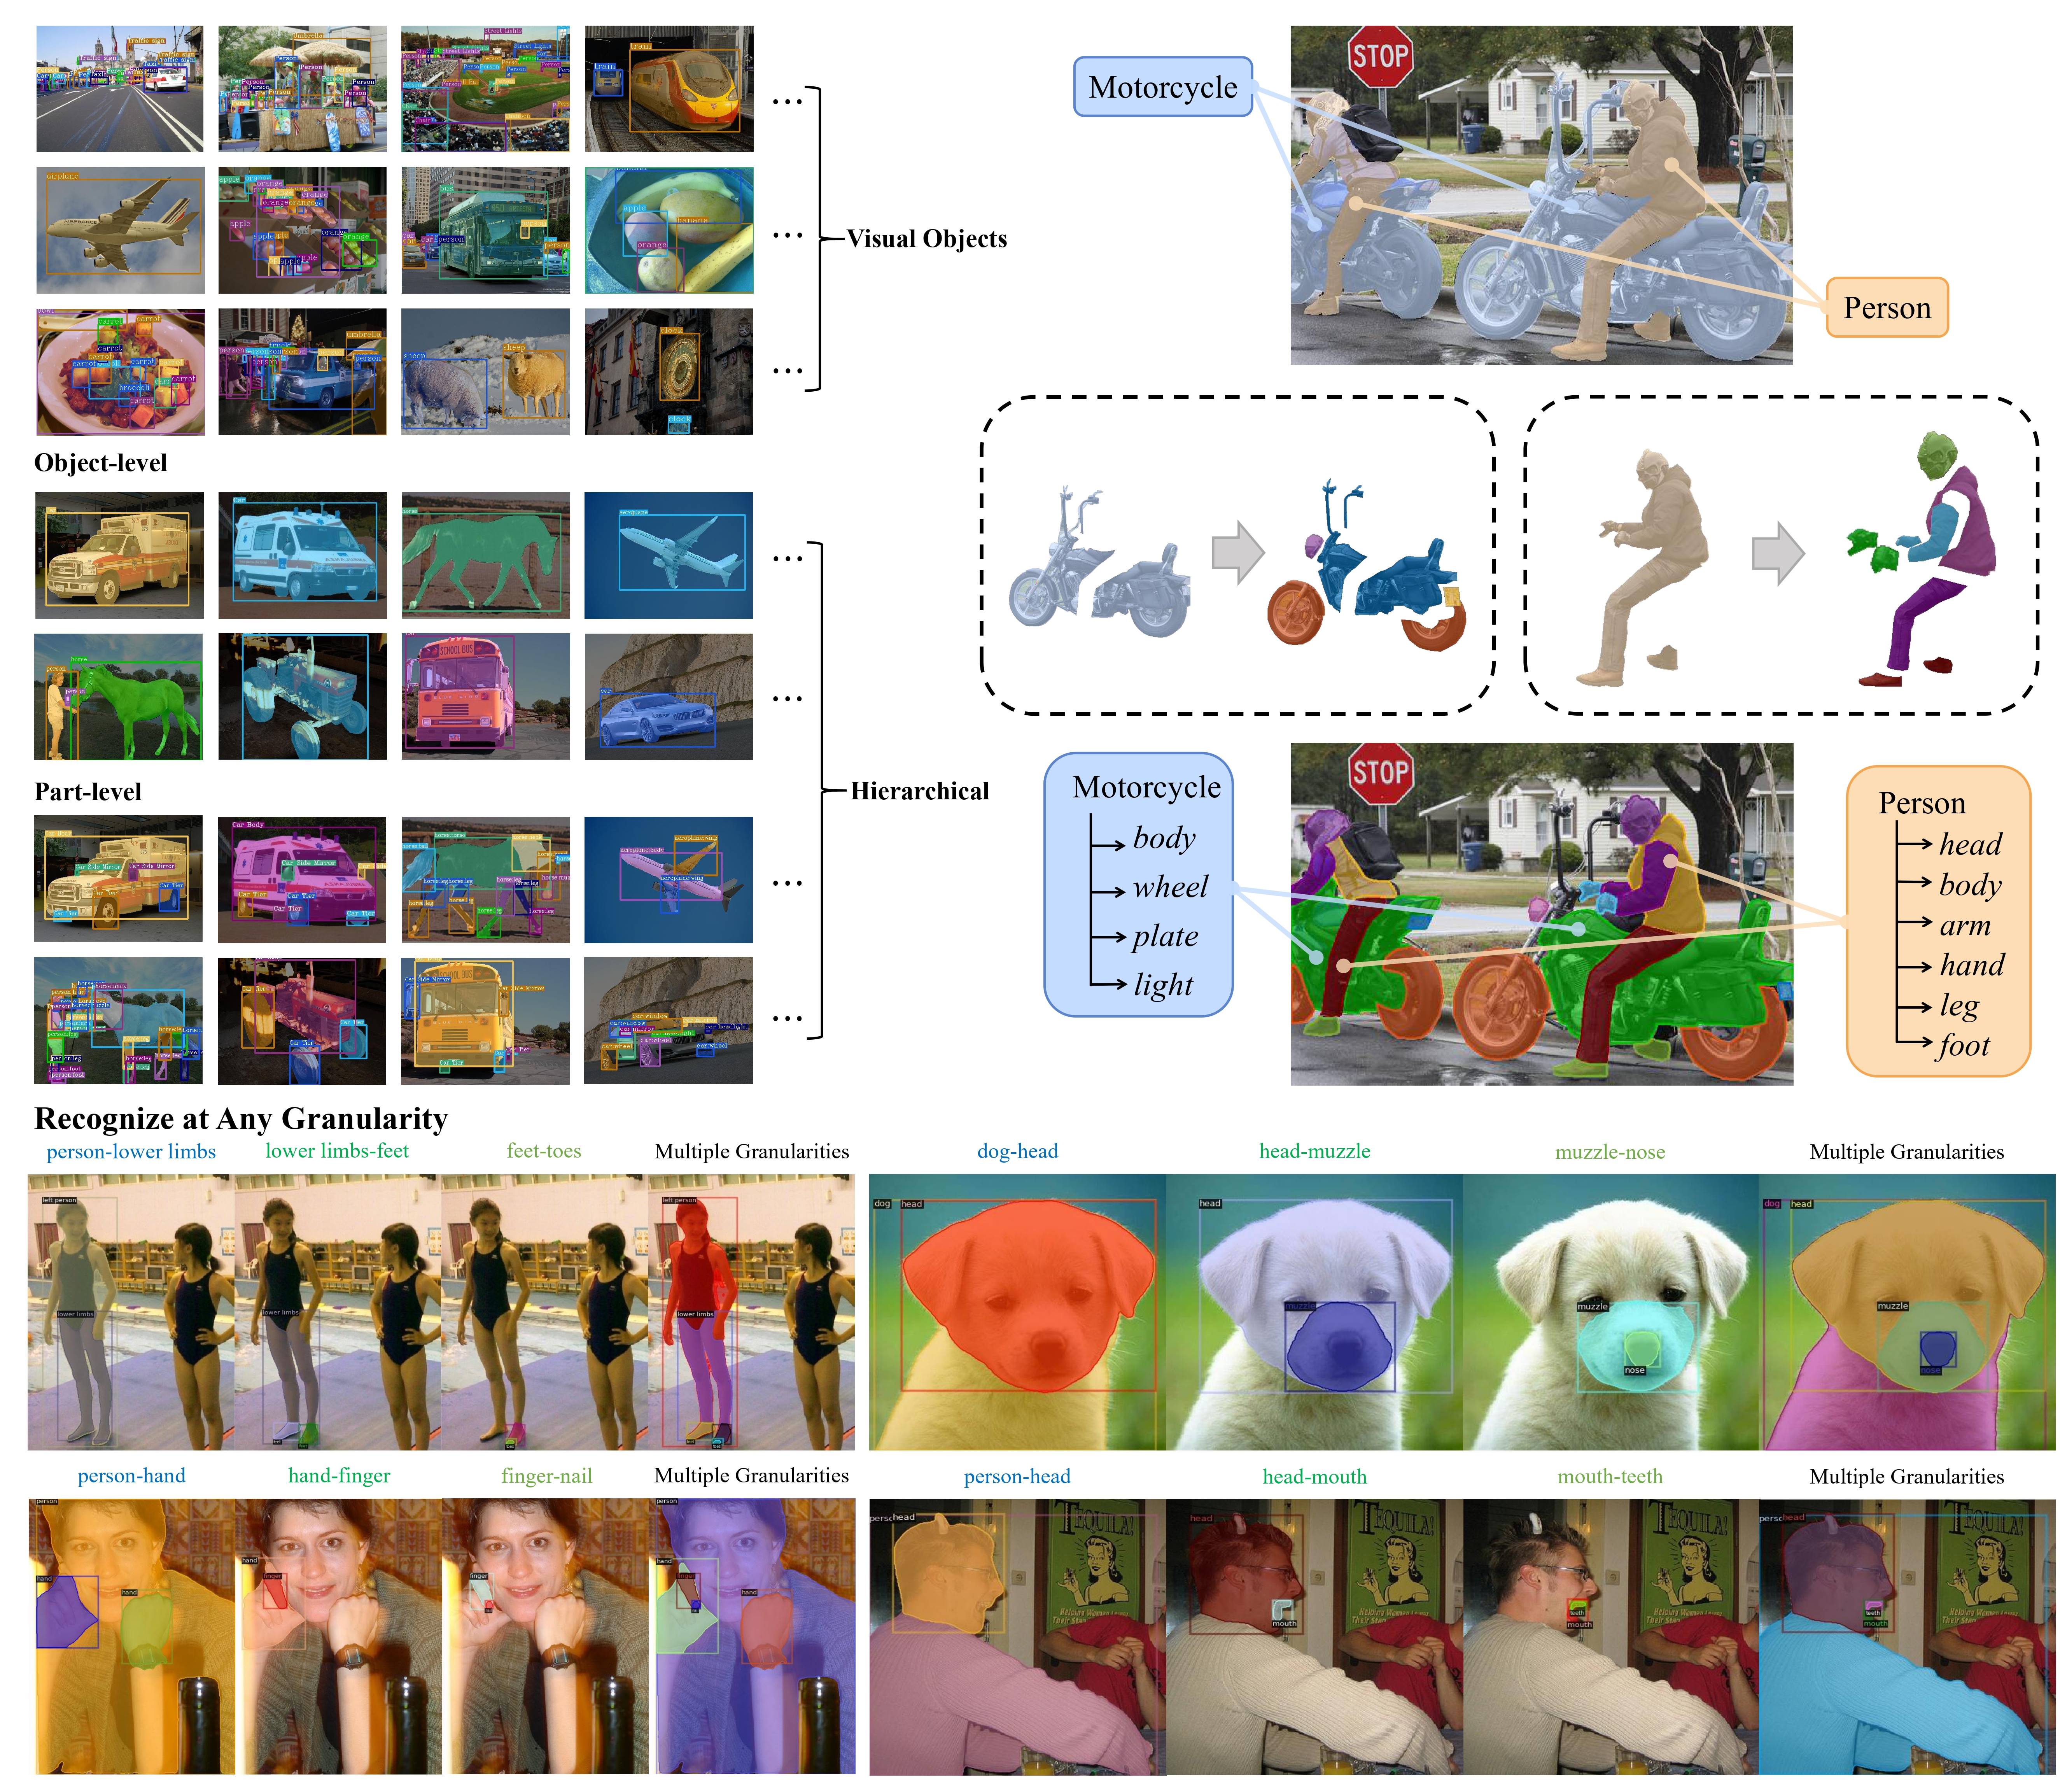
Recognizing, grounding, and segmenting objects and their parts across images and videos.
GLEE · PartGLEE
Generation-ready video latents and object-centric representations for motion and instance tracking.
VideoRAE · InstMove · IDOL · SeqFormer
03 / Publications
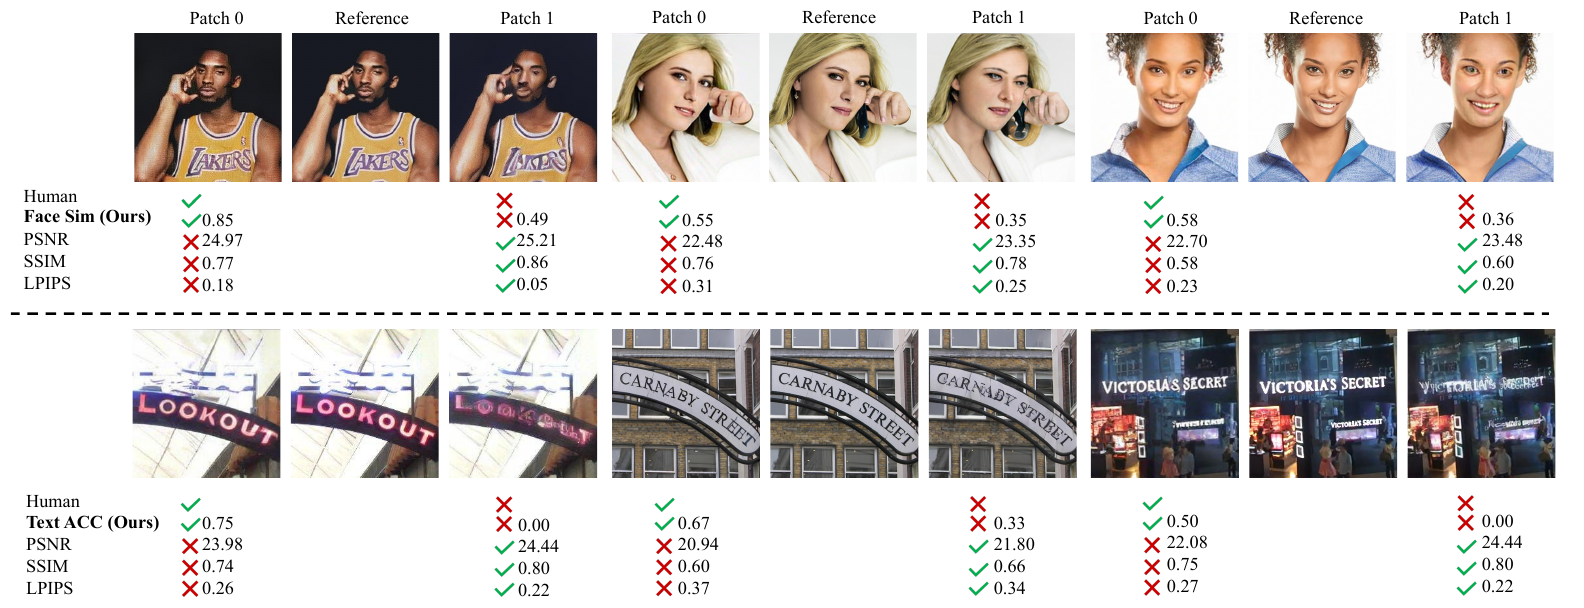 ACM MM 2026 · Oral
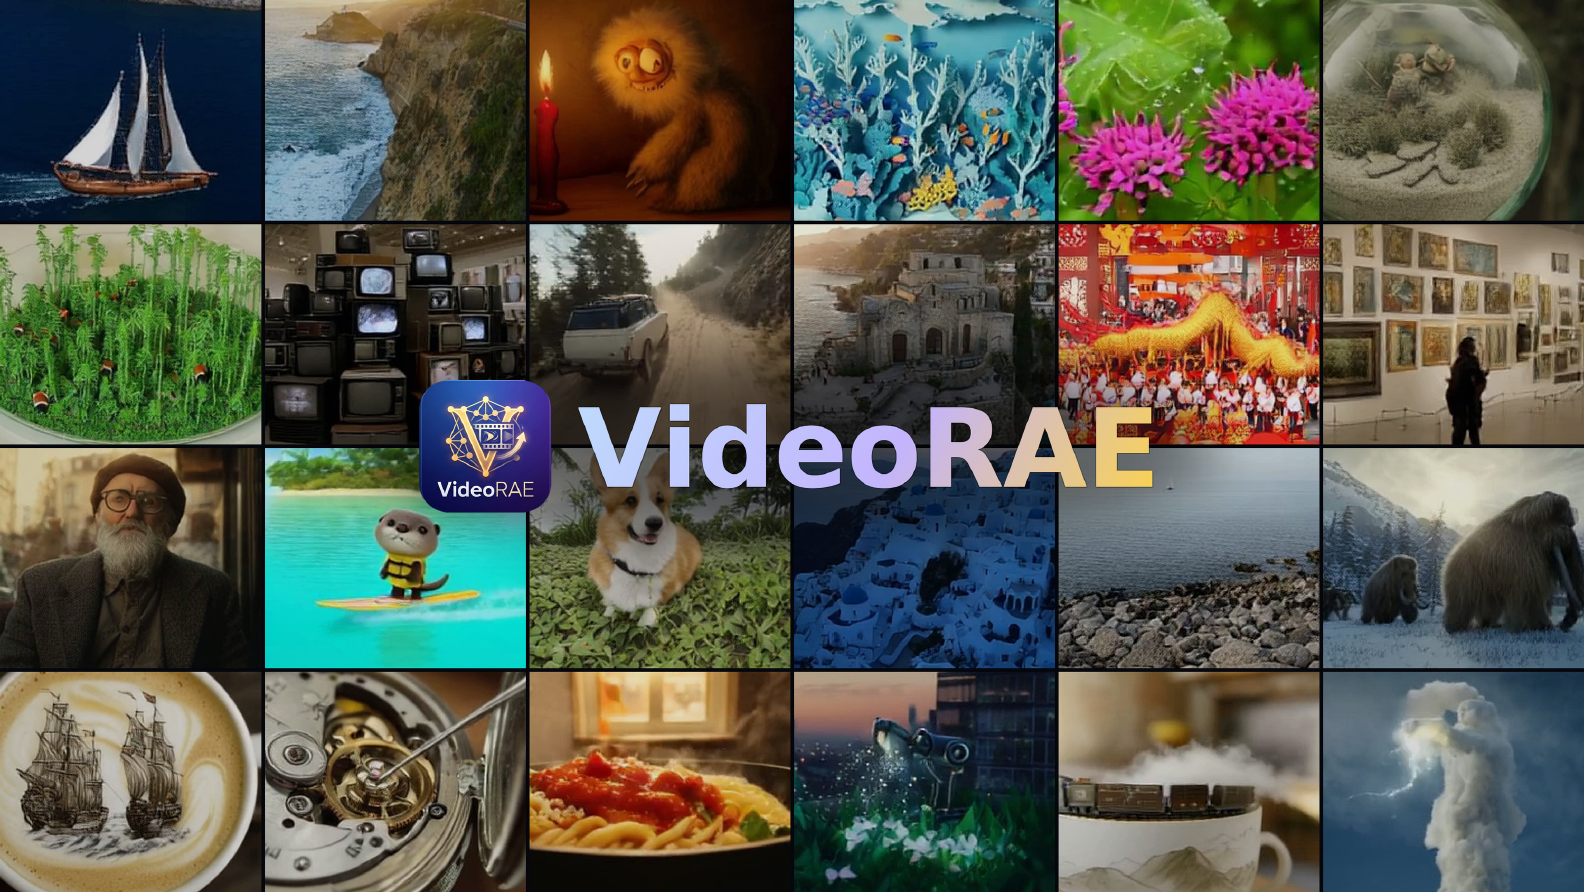 arXiv 2026 · Preprint
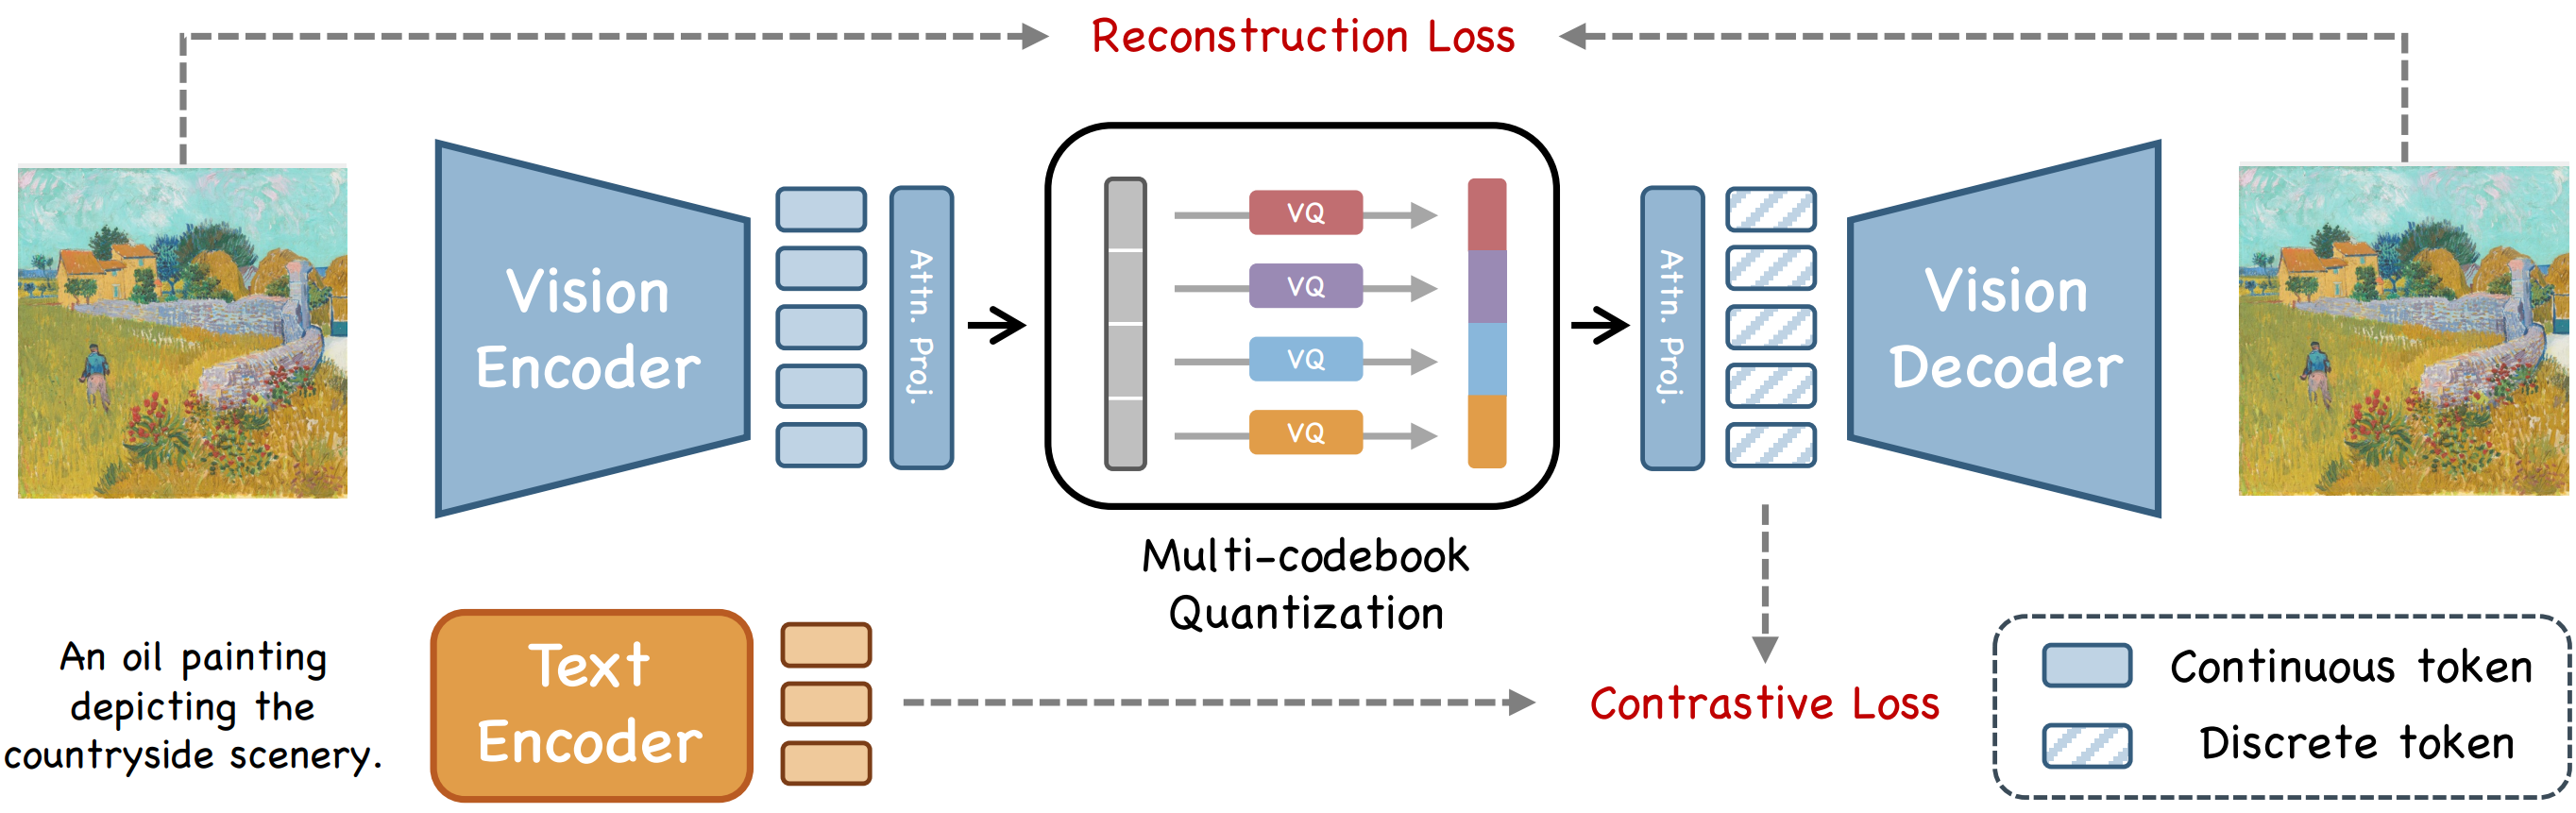 NeurIPS 2025 · Spotlight
 IJCV 2026 · Accepted 2025
 CVPR 2024 · Highlight
 ECCV 2024
 CVPR 2023
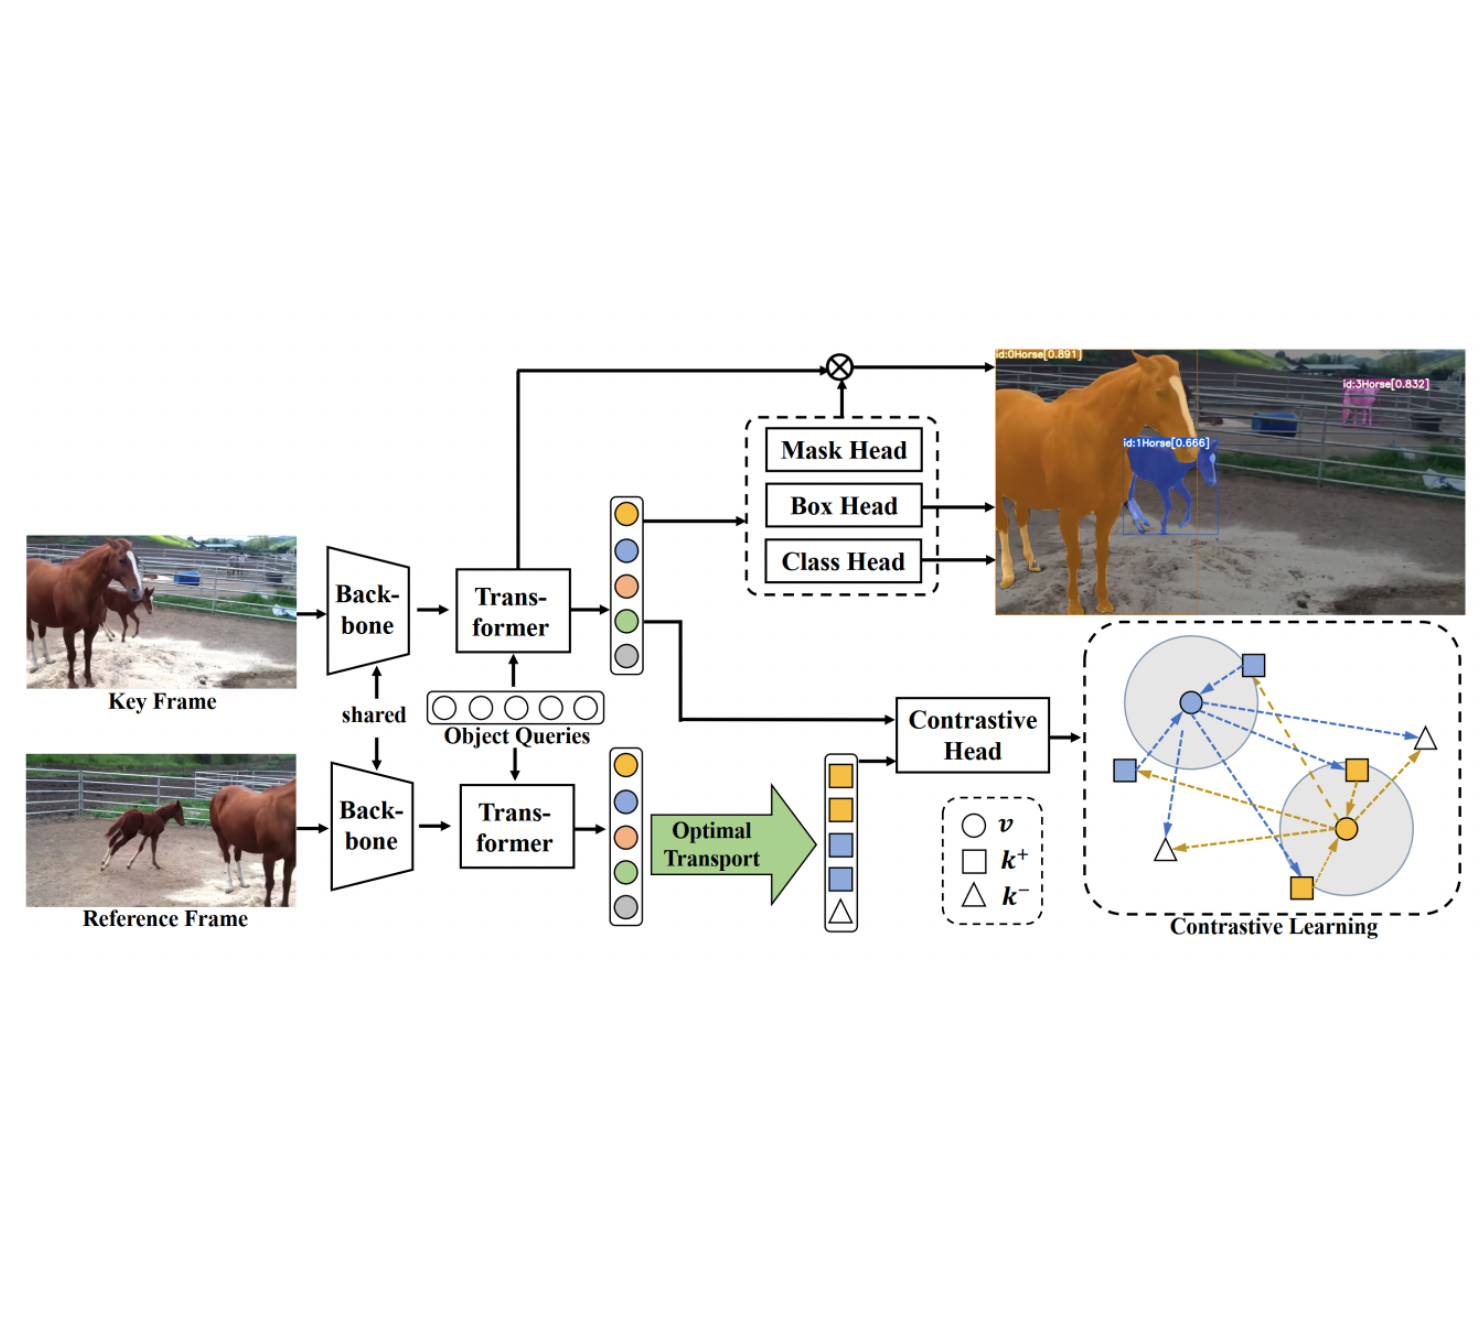 ECCV 2022 · Oral
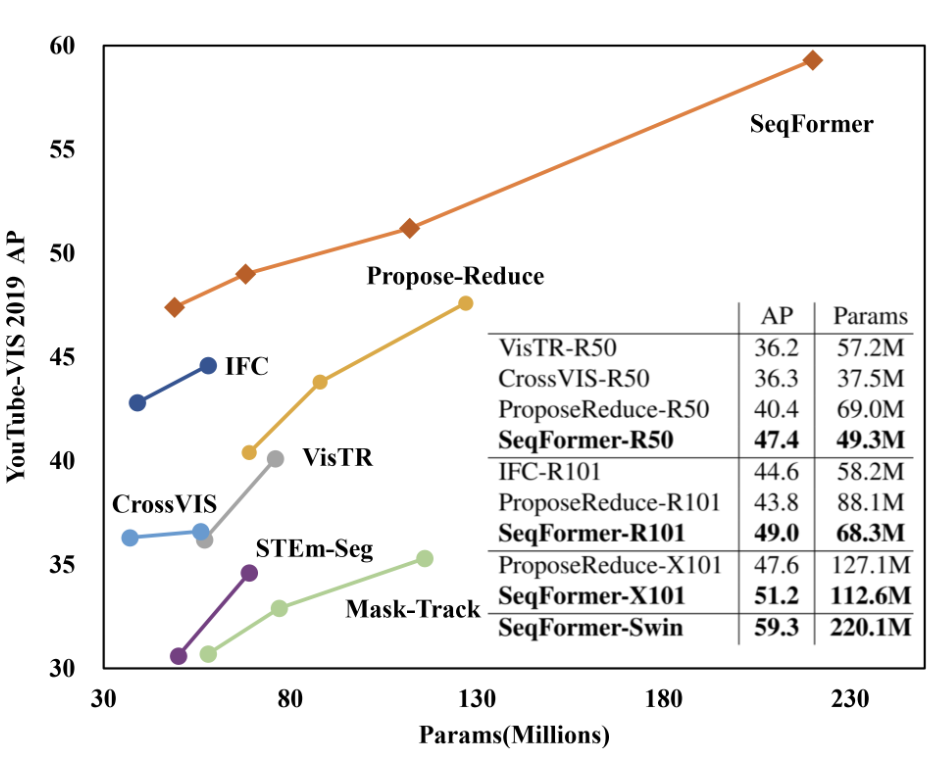 ECCV 2022 · Oral
04 / Community
Contributing to the computer vision and machine learning community.
Reviewer, 2023–2025
Reviewer, 2024–2025
Journal reviewer
05 / Contact